
When a Critical Finding Lands, the Next Step Is Already Written
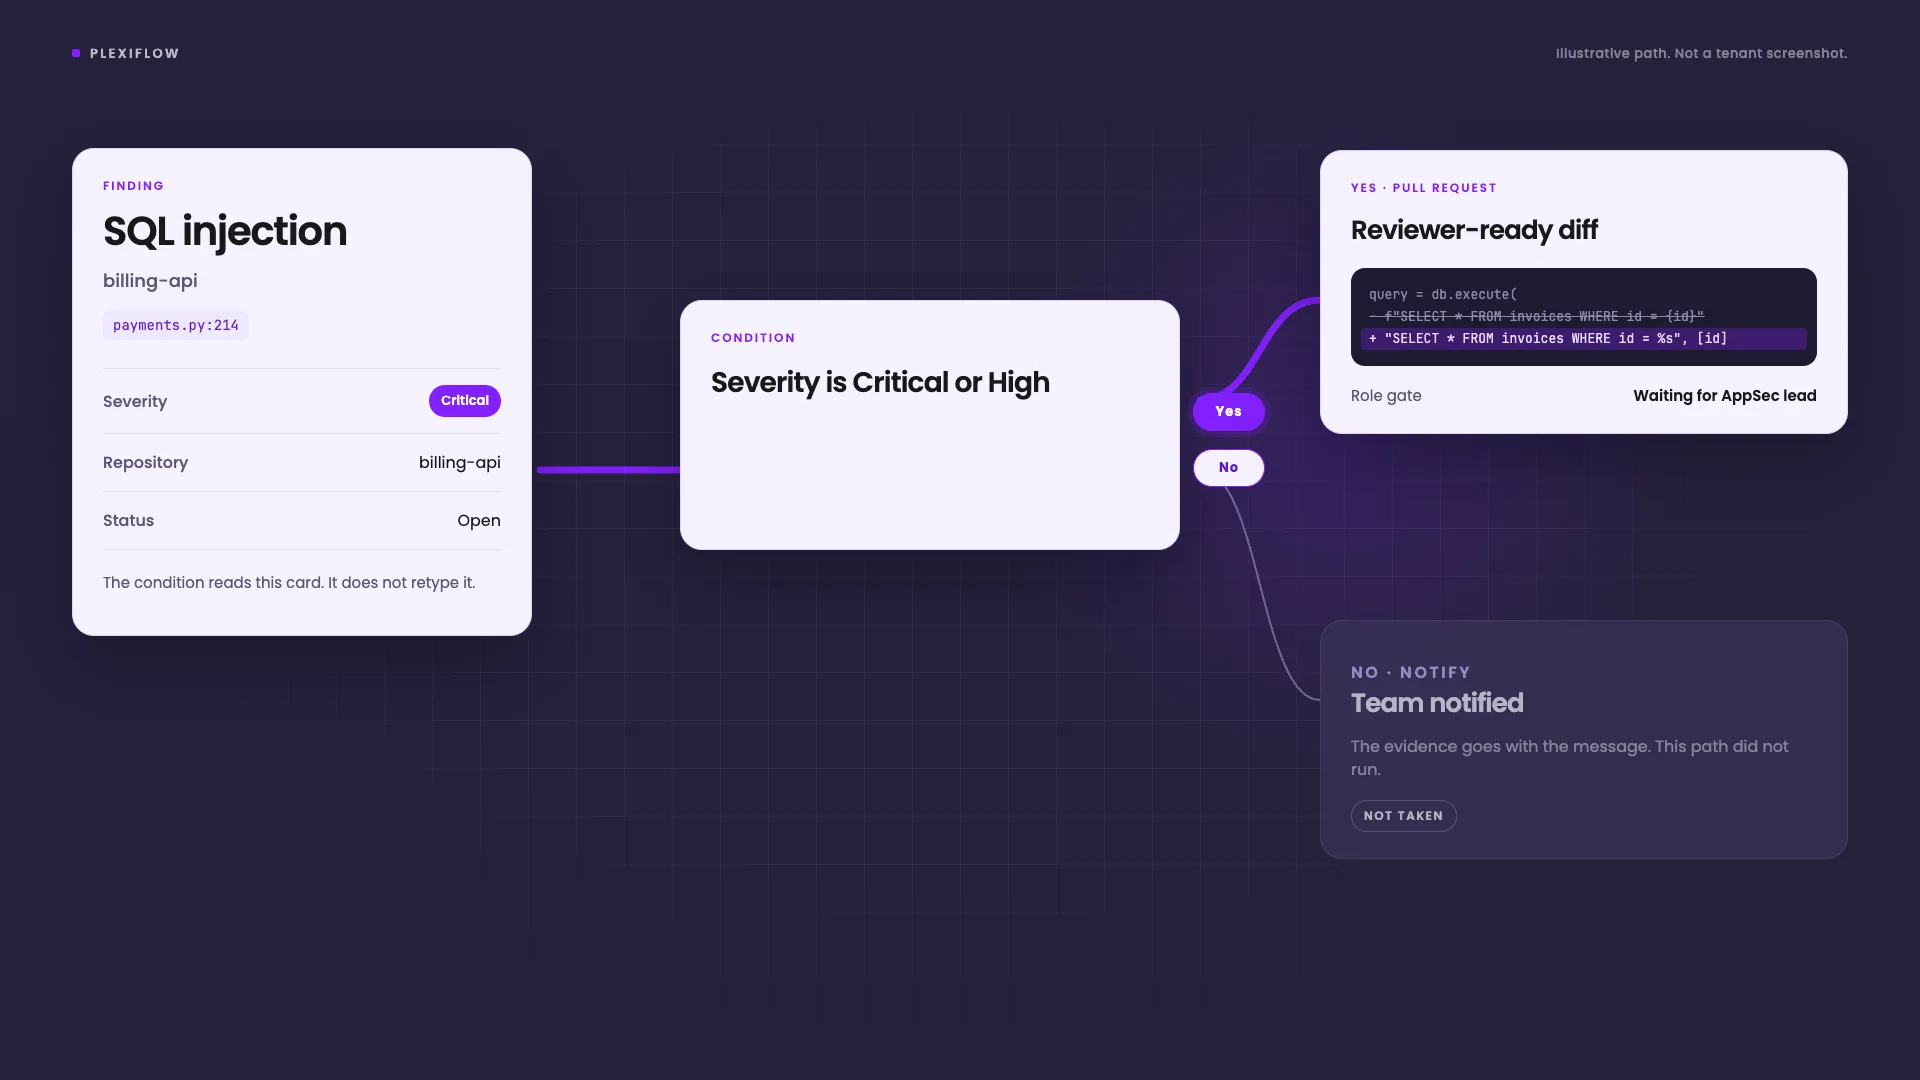
A finding should not wait in a list. PlexiFlow runs the path you already wrote: branch on severity, ask the named role, then start a fix or notify the team.
Josuanstya Lovdianchel is a Business Operations and Product professional with 4+ years of experience spanning product management, growth strategy, and AI-driven automation. He has shipped products end-to-end at scale — most notably at detikcom, Indonesia's largest digital media platform, where he delivered an ERP contributor platform to 100+ users with 100% adoption within one month of launch and led cross-functional teams across Engineering, AI, and Design. A certified Microsoft Azure practitioner with hands-on Python skills, he brings a data-first approach to every problem — from analyzing 10,000+ user reviews to surface product strategy, to building AI-powered notification systems targeting double-digit CTR uplifts. At Plexicus, he applies the same product and automation mindset to business operations, turning complex workflows into scalable systems.
A finding should not wait in a list. PlexiFlow runs the path you already wrote: branch on severity, ask the named role, then start a fix or notify the team.
Open-source AI pentesting has split into distinct categories: autonomous application pentesters, multi-agent orchestration platforms, verification-first agents, and MCP tool layers. We reviewed 10 actively developed projects and explained what each one is genuinely good at.
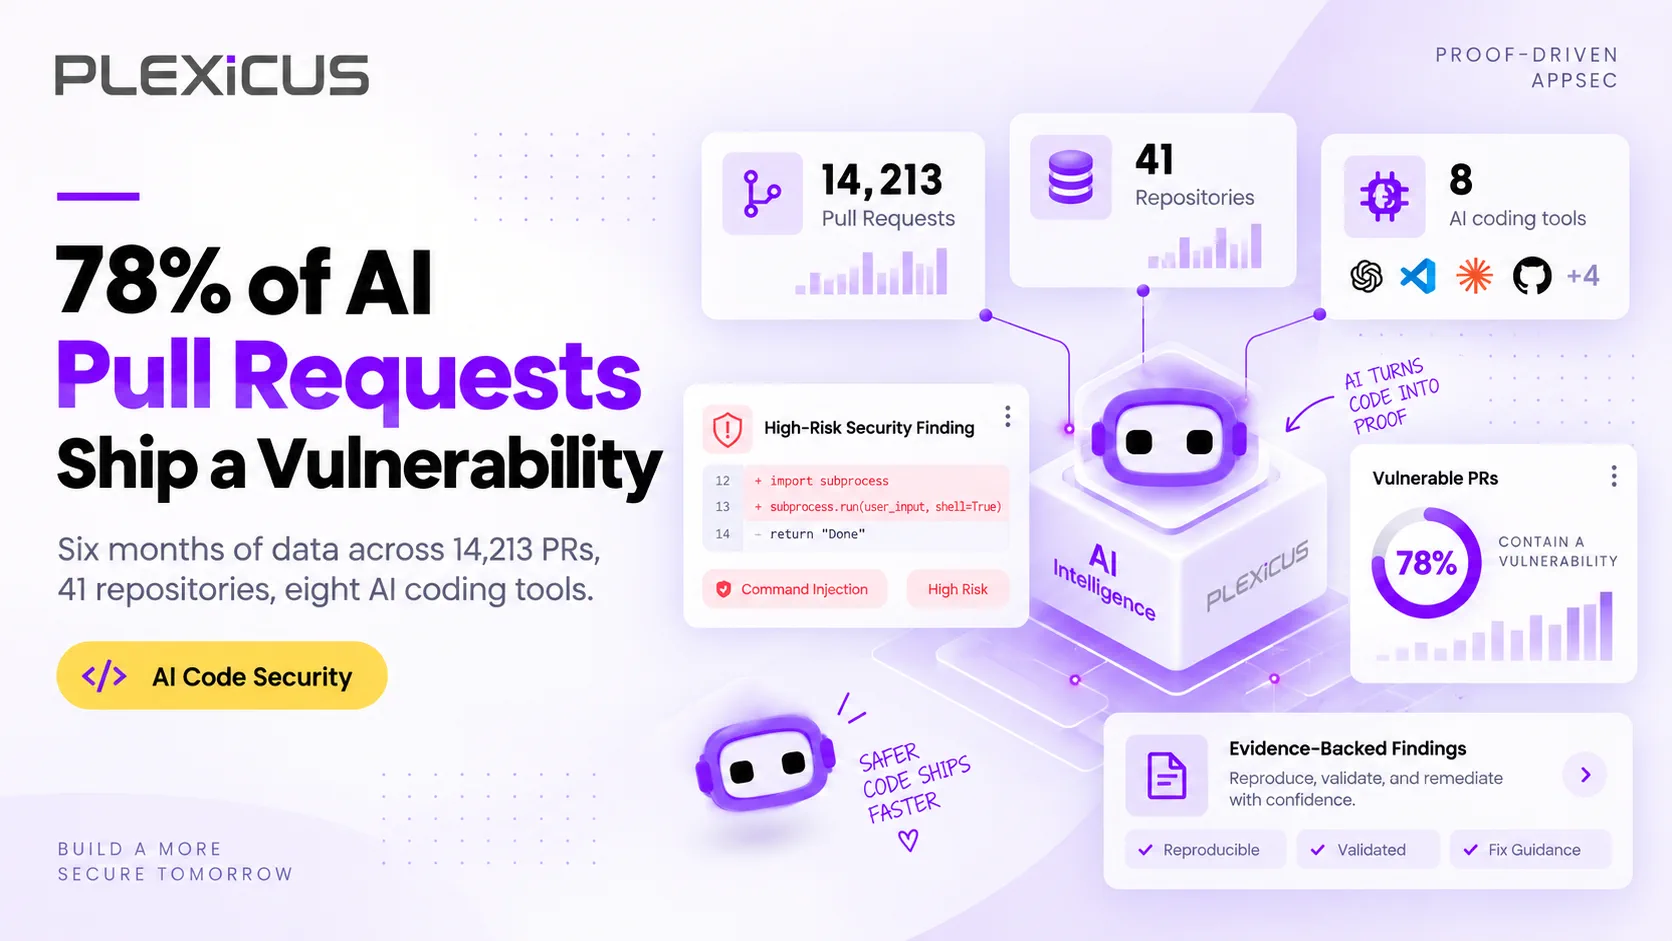
78% of 14,213 AI-assisted pull requests we scanned contained a vulnerability that survived human review. Here is how we measured it, the flaw classes, and what fixes it.
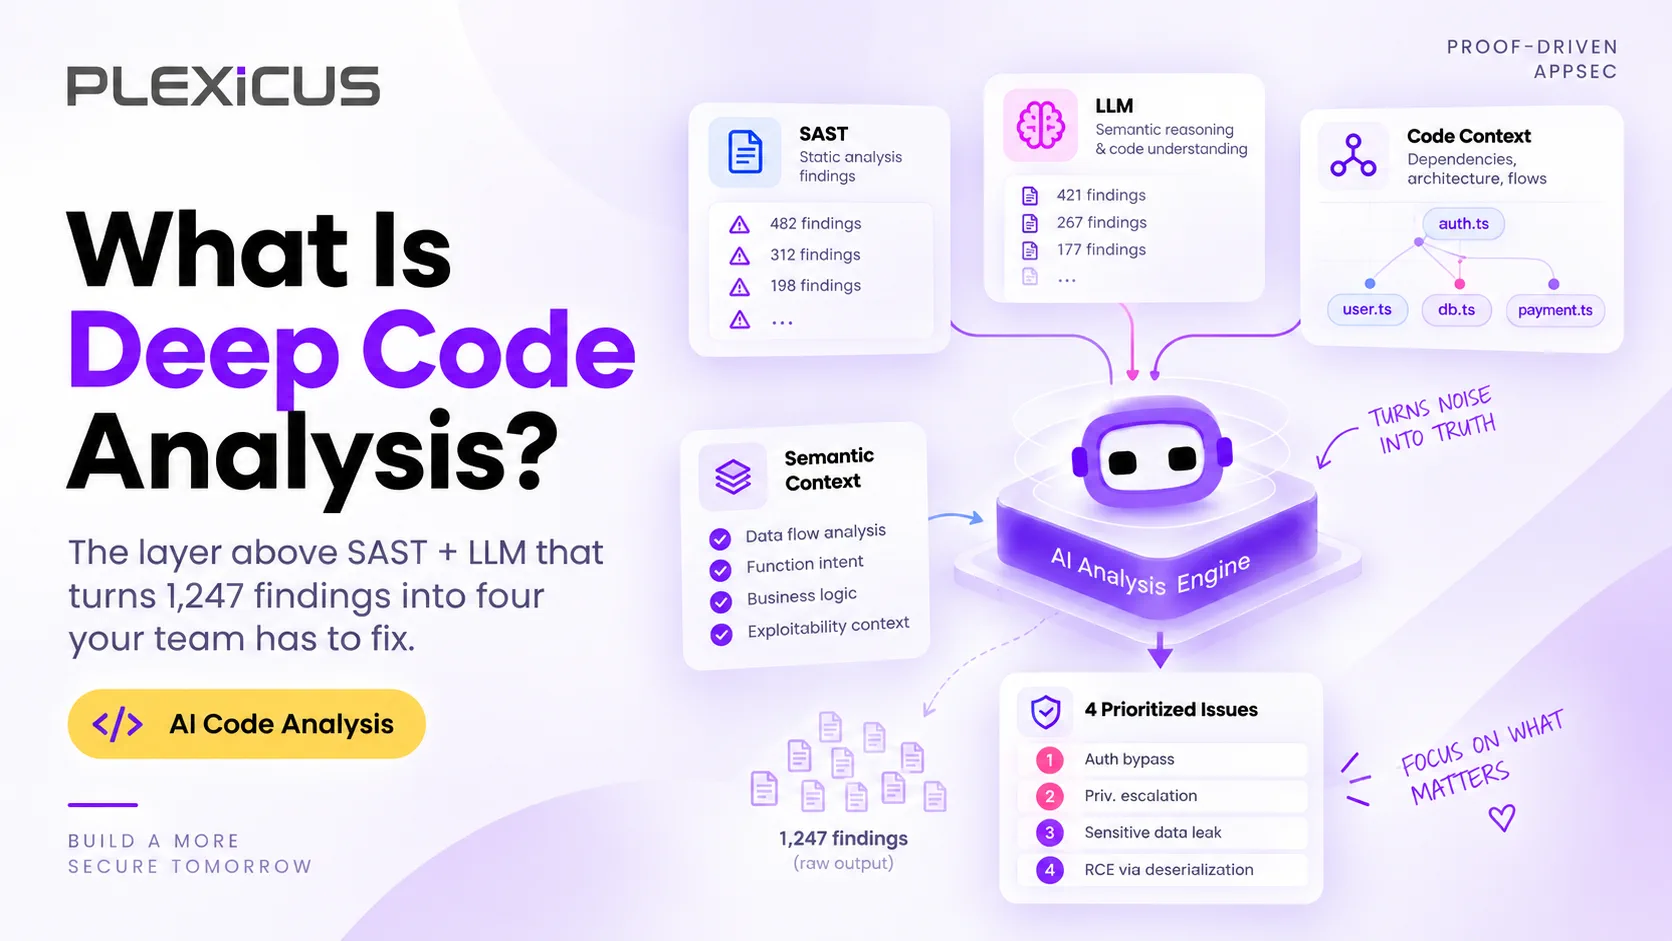
SAST false positives bury real bugs, and an LLM wrapper does not fix that. Deep Code Analysis uses reachability analysis to prove which findings are real, reachable, and worth fixing.
AI-kodingsverktøy gjør utviklere raskere – men raskere utvikling krever også bedre synlighet, sterkere gjennomgangsarbeidsflyter og mer pålitelig utbedring. Dette er en praktisk styringsveiledning for team som tar i bruk Codex, Claude Code, Cursor, Windsurf og andre AI-kodingsagenter.
Deteksjon alene kan ikke holde tritt med AI-hastighetsutvikling. AI-native utbedring er neste lag – som hjelper team med å fikse, validere og spore sårbarheter i AI-generert kode på hvert trinn av SDLC.
AI-kodeverktøy skriver nesten halvparten av all ny kode. Og 45 % av denne koden lanseres med minst én sårbarhet. Vibe coding-sikkerhet er praksisen med å sikre programvare skapt av AI – oppdage, prioritere og utbedre risikoer før de når produksjon.
Plexicus is Proof-Driven AppSec: validated findings, contextual understanding, and reviewed remediation — anchored in evidence, scoped with you.