From Alert to Fix: Closing the Loop with Proof-Driven AppSec
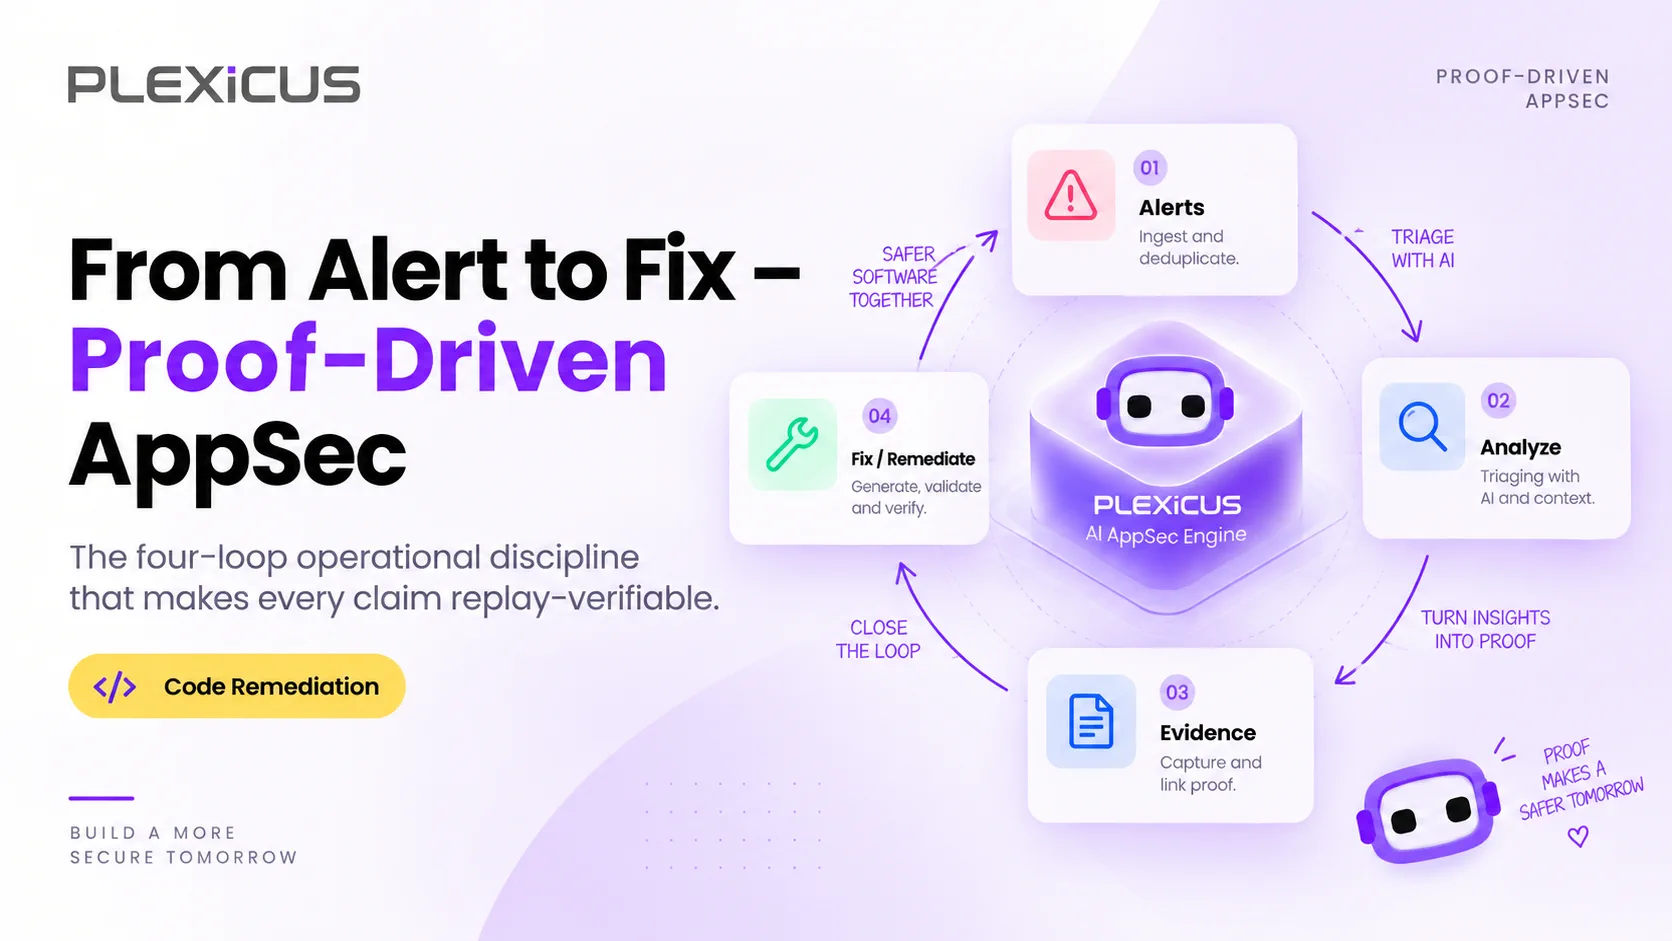
Most security programs are a series of disconnected loops — alert, triage, fix, audit, fix again, audit again. Proof-Driven AppSec closes the loop once and makes every step provable. This is the canonical definition, the four-loop structure, and what it looks like in production.
Most AppSec programs look the same. A scanner finds a vulnerability. The finding lands in a queue. A human triages it, eventually. A ticket opens. A developer picks up the ticket — when they get to it. The developer opens a PR. The PR sits in review. The review takes a week because the diff is large and the developer is the only one who understands the file. The PR merges. The CI gate passes. The finding is closed.
Meanwhile, attackers are running automated exploitation at pennies per attempt and shipping to a new device every few minutes. The multi-week median time-to-fix is not a security metric. It is a marketing slide for the attackers.
Proof-Driven AppSec is the operational discipline that closes the loop once, makes every step provable, and gets the median time-to-fix from weeks to days. This is the canonical definition.
What Proof-Driven AppSec Is
Proof-Driven AppSec is the discipline of running application security programs where every claim is grounded in evidence an auditor, a developer, or a CI gate can re-run. Not CVSS scores. Not severity tags. Not “high/medium/low.” A reproducible artifact attached to the finding.
Three properties define the practice:
- Every finding has a path. Not a regex hit. Not a pattern match. A reachability path from a real input source to a real capability-bearing sink, bound to a specific file and line number.
- Every finding has evidence. A request that can be re-run, a CI job that can be replayed, a sandbox state that can be resumed. If a finding cannot be reproduced, it is not a finding — it is a hypothesis.
- Every fix has an evidence chain. The patch came from the same finding. The patch closes the original exploit. The patch was reviewed with the original evidence attached. The patch’s regression test is the original exploit, inverted.
That is the practice. Anything that does not check all three is a screenshot of an AppSec program, not an AppSec program.
The Four-Loop Structure
The operational pattern has four loops. Each loop has a job. Each handoff preserves the evidence.
Loop 1 — Detect
The first pass scans the codebase (and the IaC that defines the runtime) and produces a graph of hosts, endpoints, parameters, and capabilities. Findings are positions in the graph, not lines in a file.
This is what Deep Code Analysis does. The output is a set of proposed findings — each bound to a graph node, a reachability path, a capability class, and a line number.
Loop 2 — Verify
The second pass takes each proposed finding and tries to reproduce it. The agent that performs this pass is not the agent that proposed the finding. This is the critical step. Self-consistency is not verification.
The output of Loop 2 is a smaller set of verified findings, each with the evidence attached. Findings that do not reproduce are discarded with a stated reason. The reason codes matter — they are how your team debugs the pipeline later. Common ones include: no real path from a public endpoint to the sink, an upstream check that makes the finding inert, a runtime control that neutralises it, or the second agent could not reproduce the result.
Loop 3 — Fix
The third pass takes each verified finding and drafts a reviewer-ready patch. The patch is not a generic fix. It is the minimum change that removes the reachability path while preserving business logic. The patch includes regression tests (the original exploit becomes a test). The patch includes documentation updates.
This is what a structured remediation workflow does. The output is a pull request, not a code snippet.
Loop 4 — Audit
The fourth pass ensures that the patch closes the original finding. The verifier re-runs the original exploit against the patched branch. If the exploit reproduces, the patch is reverted. If the exploit is mitigated, the patch is signed and the finding is closed.
The output of Loop 4 is an audit record: original finding, graph node, evidence reference, patch diff, regression test result, reviewer approval, deploy timestamp. One record per finding. Signed. Replayable.
Why This Is Not “AI-Native AppSec” With Better Marketing
The term “AI-native AppSec” was useful when it meant “the scanners use machine learning models.” Every scanner uses machine learning models now. The differentiator is not whether AI is involved. It is whether the AI is grounded.
Three failure modes of the AI-native era:
- AI that summarises findings without grounding. The model reads the SAST output and produces a more readable PDF. The auditor still cannot re-run anything.
- AI that proposes fixes without verification. The model writes a patch. The patch compiles. The patch changes the meaning of the code. A human reviewer is expected to catch this. They cannot, at scale.
- AI that runs without evidence. The model explores the application. It finds something interesting. It reports it as a finding. The report cannot be reproduced.
Proof-Driven AppSec is the answer to all three. The structure is the bar:
- Detection must produce a path, not a pattern.
- Verification must be independent, not self-consistent.
- Fix must be grounded in the same evidence, not a generic suggestion.
- Audit must be replayable, not narrative.
Anything that does not check all four is the same AppSec program with a different logo.
The Operational Loop in Practice
Across the Plexicus customer base running the full four-loop pattern, the practical effect is the same shape: triage time compresses from days to minutes, false positives drop after verification, and the time-to-merge drops because the reviewer is reading a small, evidence-backed diff instead of an unverified list.
Two numbers define whether the practice is working: how often the auditor can re-run the evidence and confirm the finding, and how often the auditor accepts the patch as fixing what the finding claimed. Everything else is throughput.
The exact medians vary by codebase, language mix, and CI maturity. The pattern is what scales.
What the Threat Landscape Demands
The threat landscape in 2026 is structurally faster than the defender cycle:
- Time-to-exploit for newly published vulnerabilities has compressed from years to hours. Sub-day is now the norm for high-profile targets.
- Open-source offensive AI tooling has multiplied. The fastest tool-class emergence in offensive security history.
- Single-operator ransomware crews have hit hundreds of devices across dozens of countries in a single campaign.
- A meaningful share of exploited vulnerabilities are active before a CVE is published.
The attacker pipeline is already proof-driven. They verify their exploits before they ship them. They replay their payloads. They audit their results. The asymmetry is not “attackers use AI and defenders don’t.” The asymmetry is “attackers use a closed loop and defenders use a series of open queues.”
Proof-Driven AppSec is the operational pattern that closes the defender’s loop.
What This Looks Like for a Real Engineering Team
The four-loop structure is not a vendor-specific thing. The pattern can be implemented with the tools your team already has:
- Loop 1 (Detect) — static analysis that produces reachability paths. Plexicus Deep Code Analysis, or any scanner that binds findings to the call graph instead of the line number.
- Loop 2 (Verify) — a scoped pentest engagement. Plexicus AI Swarm Pentest, or a manual pentest engagement with evidence capture.
- Loop 3 (Fix) — a patch generator with regression tests. Any AI coding workflow with explicit instructions to ground patches in the original finding.
- Loop 4 (Audit) — a CI re-test hook that runs the original exploit against the patched branch.
The four loops have to be wired together. The evidence from Loop 2 has to land in Loop 3. The patch from Loop 3 has to be re-verified by Loop 2. The audit record from Loop 4 has to include the evidence references from Loops 1, 2, and 3.
If any of those handoffs loses the evidence, the loop is broken. The practice stops being proof-driven.
The Bar for 2026
Three questions to ask your security program:
- Can your scanner produce a reachability path for every finding? If the answer is “no, just a line number,” your triage queue is going to keep growing.
- Can your pentester re-run the finding against a clean build? If the answer is “we’d have to set up a new engagement,” your evidence trail is not replayable.
- Can your developer open the PR with the original exploit attached? If the answer is “they’d have to ask the security team to re-find it,” your audit trail is not continuous.
If all three answers are “yes,” you are running Proof-Driven AppSec. If any of them is “no” or “kind of,” the gap is in the evidence handoff, not in the tooling.
Where This Goes
In the next two years, every regulator is going to ask the same question: can you replay the evidence that proved this control was working when the incident happened? Teams running Proof-Driven AppSec will answer “yes” with the original artifact. Teams running the old pattern will answer “we have a PDF.”
The investment to close the gap is not large. The discipline to keep it closed is.
Related reading:
- What Is Deep Code Analysis? — Loop 1
- 78% of AI-Generated PRs Contain a Vulnerability — why verification is the new bottleneck
- The Autonomous Remediation Playbook — Loop 3 in detail
- OWASP MAESTRO Field Guide for Threat Modellers — the reference architecture for the agents running the loops