Jev Doesn't Chat. It Decides. Why That Matters for Cybersecurity.
Jev is designed to return typed decisions instead of prose. That distinction could change where semantic judgment fits in security workflows, provided teams retain policy, fallbacks, verification, and human review.

For years, the AI race has been dominated by one question: which model can generate the best answer?
TypeSafe AI is asking a different question: what if software does not need an answer at all? What if it needs a decision?
On September 15, 2026, TypeSafe AI introduced Jev, the first model in a category the company calls System One Models. Instead of generating prose token by token, Jev receives context and predefined questions, then returns typed decisions: choices, scores, or probabilities that software can consume directly.
That distinction sounds subtle. For cybersecurity, it may not be.
Security systems make an enormous number of small decisions:
Is this authentication attempt suspicious? Does this process need to be killed? Is this vulnerability likely exploitable? Does this agent action exceed its permissions? Should this alert be closed, queued, or contained?
Traditional rules are extremely fast and inexpensive, but brittle. Large language models understand context far better, but using a frontier model for every alert, tool call, process event, or transaction introduces meaningful latency and cost. Jev is interesting because it attempts to occupy the space in between.
From generating language to making decisions
A conventional LLM might receive an alert and return an explanation:
“The event appears suspicious because the process accessed LSASS memory and no approved maintenance window was found.”
That is valuable to a human analyst. But software often throws most of the prose away and extracts something closer to this:
risk = critical
action = contain
confidence = 0.97
Jev removes the prose-generation step. The application defines the possible outputs in advance; the model evaluates the state and returns probabilities directly. TypeSafe describes this as “unstructured state in, typed probabilistic decisions out.”
Traditional LLM                     Jev

Security event                      Security event
     ↓                                   ↓
Generate reasoning                  Evaluate predefined questions
     ↓                                   ↓
Generate tokens                     Typed probabilities
     ↓                                   ↓
Parse and validate schema           Decision
     ↓
Decision
The difference is architectural. TypeSafe says Jev samples outputs in parallel, while an autoregressive language model emits tokens sequentially. Its Vercel AI Gateway integration describes the API as supporting Choice, Score, and Boolean-style decisions.
A cybersecurity evaluation already exists
This is not purely theoretical. One of TypeSafe’s published workflow evaluations is called Security Incidents. The workflow starts when an alert fires on a laptop or server and incorporates alert, asset, owner, open-ticket, registered-device, maintenance, and authorization context.
It first asks whether activity appears unauthorized, whether existing records explain it, and how strong the evidence is. If containment may be needed, it asks further questions about credentials, active sessions, mail, persistence, processes, network activity, and spread before choosing an action.
The available outcomes include notifying a user, escalating, killing a process, disabling an account, and urgent escalation. That resembles what teams already build through SIEM rules, SOAR playbooks, detection engineering, and analyst triage. The potential difference is that parts of the branching logic become semantic rather than entirely deterministic.
Security is full of expensive “if statements”
Consider a basic rule:
IF failed_logins > 10
AND source_country != usual_country
THEN escalate
It is fast, predictable, and auditable. But a real event may include a corporate-managed device, a valid business trip, an approved VPN change, and successful MFA. The question is no longer a simple threshold.
A decision model could return a structured view of that context:
Is activity unauthorized?              0.18
Does approved activity explain it?     0.94
Evidence of compromise?                0.12
Immediate containment required?        0.04
The surrounding security policy must still determine what those numbers are allowed to trigger.
The model estimates. The security system enforces.
Early independent testing is more useful than launch headlines
TypeSafe reports 70–500 ms end-to-end response times and input pricing of $0.042 per million tokens. It also reports as much as 193.6× faster and 444.6× cheaper performance on its workflow evaluations. Those are vendor results, not a universal benchmark. TypeSafe explicitly says the largest gains are likely at the higher end of real-world outcomes and acknowledges that its workflows were authored by members of its model-capabilities team.
The most useful early external evidence comes from the Nexus Agent team’s evaluation. Nexus reports testing 19,118 real moments from agent operations and making 36,218 Jev calls. In one 469-case guardrail comparison, it tested rules, Claude Haiku 4.5, Claude Sonnet 5, and Jev.
| System | Error when it decided | Coverage | Total errors with fallback | Typical response | Cost / answer |
|---|---|---|---|---|---|
| Rules | 31.6% | 100% | 148 | ~0.05 s | $0 |
| Claude Haiku 4.5 | 13.7% | 73% | 99 | 6.0 s | $0.0065 |
| Claude Sonnet 5 | 7.0% | 67% | 92 | 6.3 s | $0.0178 |
| Jev | 1.8% | 58% | 90 | 0.66 s | $0.00008 |
The important detail is coverage: Jev did not decide every case. It acted on 58% and deferred the remaining 42% to existing rules when its confidence was insufficient. That makes 1.8% very different from a claim of universal 98.2% accuracy.
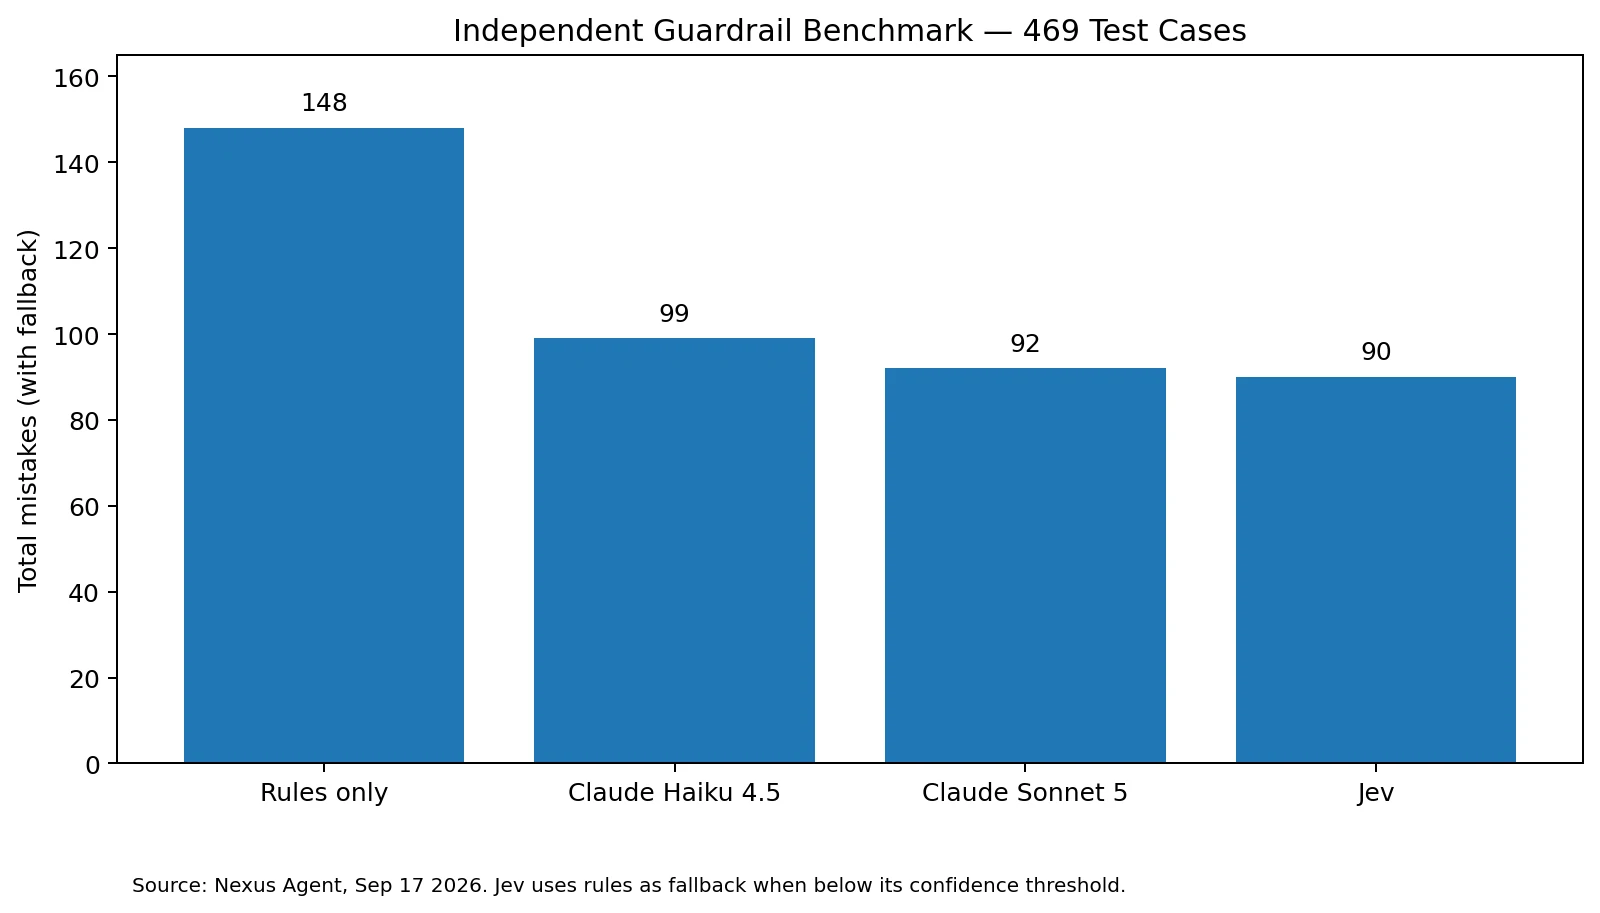
Figure 1. Total mistakes with fallback across 469 guardrail test cases. Source: Nexus Agent, September 17, 2026.
This may be the design pattern that matters most:
AI answers what it is confident about
              ↓
        uncertain cases
              ↓
stronger model / existing control / human
In cybersecurity, knowing when not to automate can be as important as knowing when to automate.
Reality is slower than a 70 ms headline — and still useful
The Nexus evaluation reports a median latency of 0.68 seconds across 36,218 calls from a laptop in Europe, a 95th percentile of 1.79 seconds, and 2.2% of calls over its three-second limit. It also reports roughly 230–350 ms individual calls when connections were reused.
That does not mean every decision lands in 70 ms. It does suggest semantic judgment may be fast enough for workflows where a multi-second frontier model would be impractical.
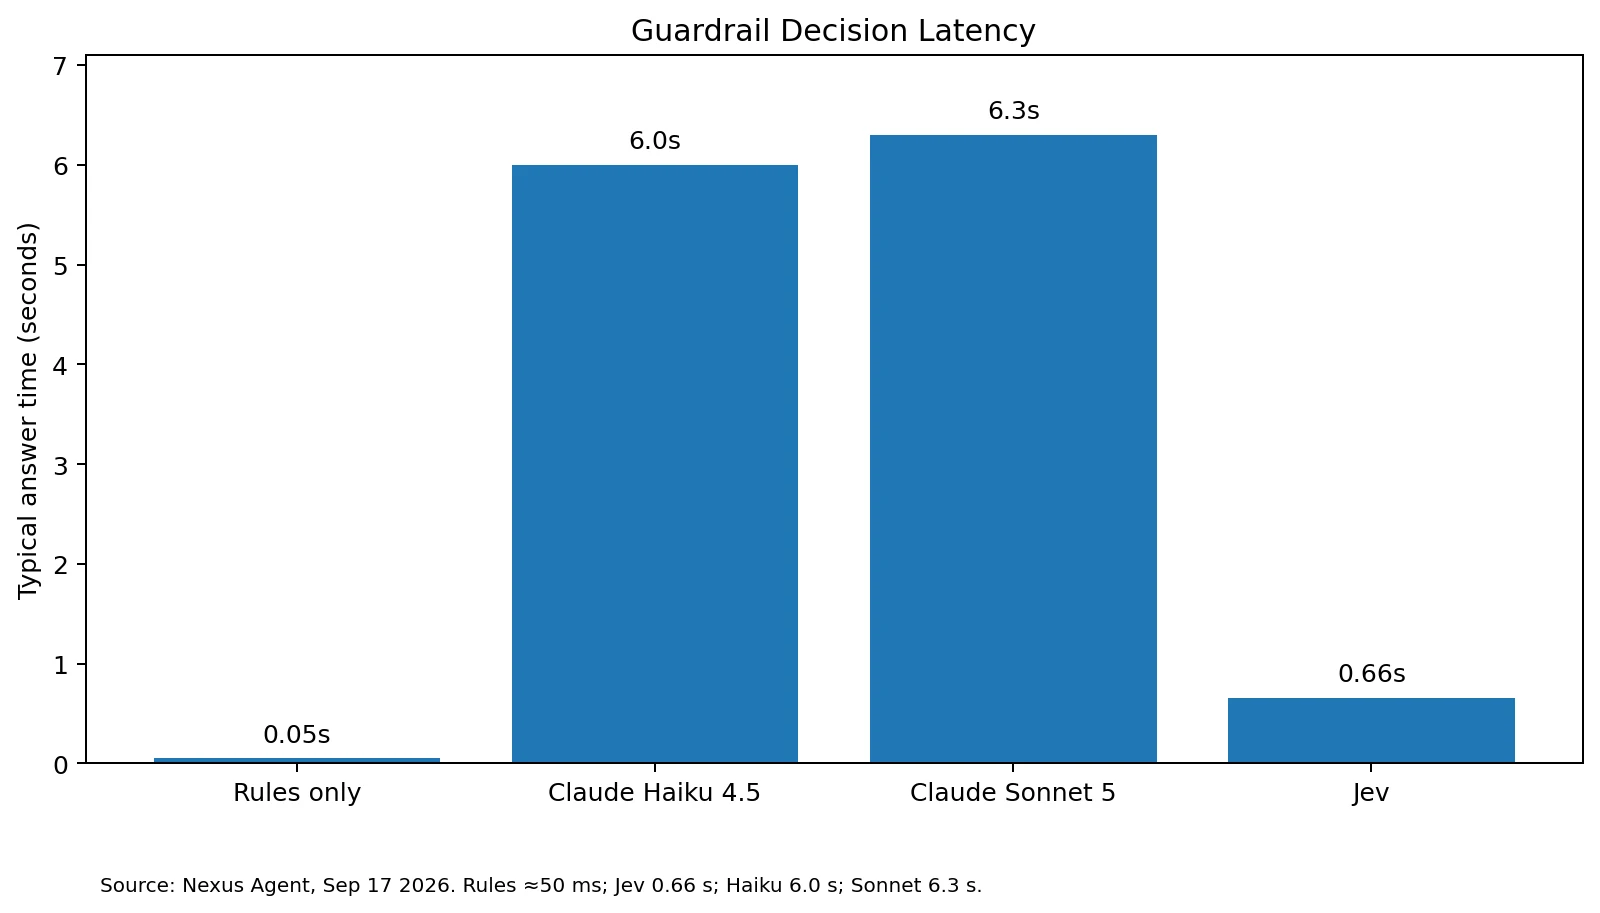
Figure 2. Typical guardrail decision latency reported by Nexus Agent. Source: Nexus Agent, September 17, 2026.
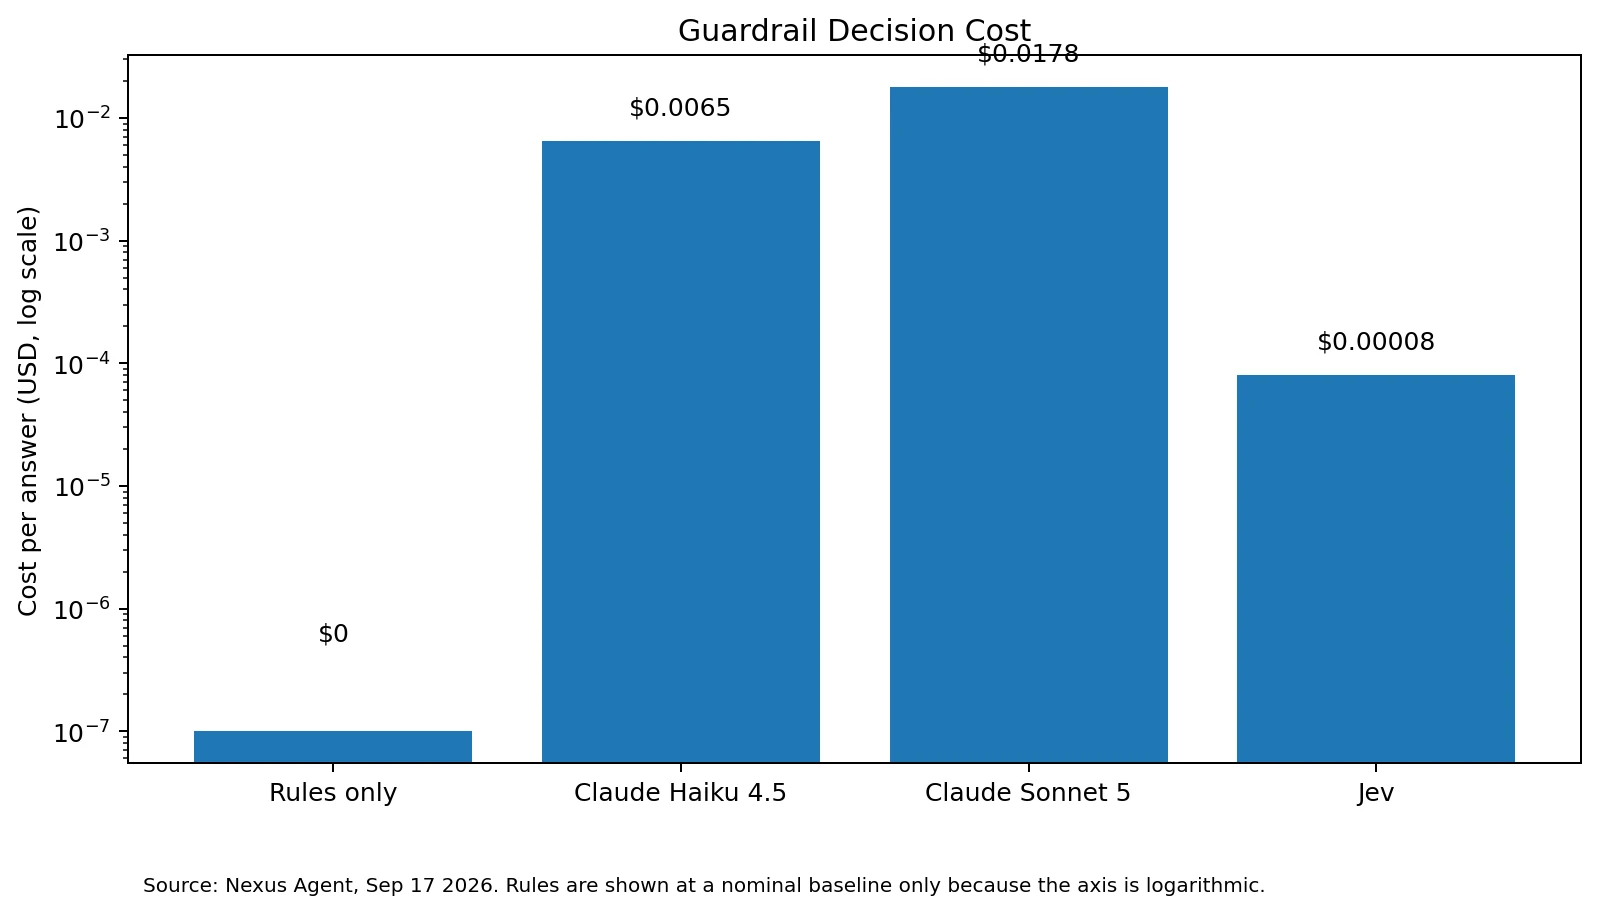
Figure 3. Cost per guardrail decision, logarithmic scale. The rules baseline is shown nominally because the axis is logarithmic. Source: Nexus Agent, September 17, 2026.
Where this could matter for cybersecurity
SOC triage
Security operations centres already work as funnels:
Millions of events
        ↓
Detection rules
        ↓
Thousands of alerts
        ↓
Analysts
Decision models could add inexpensive semantic judgment earlier in the funnel:
Millions of signals
        ↓
Detection
        ↓
Decision model
   ↙      ↓       ↘
benign  uncertain  high-risk
  ↓        ↓          ↓
close    reason     respond
          ↓
      LLM / human
The goal is not to replace analysts. It is to reserve expensive reasoning and human attention for events where they provide the most value.
Guardrails for AI agents
An autonomous agent may read email, modify files, query databases, run shell commands, call APIs, change infrastructure, or send messages. Every invocation introduces a security decision.
Before an agent executes an irreversible action, a decision layer might assess:
Destructive action?              0.999
Reversible?                      0.003
Explicitly authorized?           0.21
Human confirmation required?     0.998
The policy engine can then block or escalate the action regardless of what the primary reasoning model wants to do. This is consistent with TypeSafe’s Agent Trace Observability evaluation, which examines instructions, tool calls, results, and authorization boundaries.
The pattern resembles EDR for AI agents: not merely recording which command executed, but deciding whether the action was appropriate for the context, permissions, and intended task.
DLP, IAM, phishing, fraud, and vulnerability prioritisation
Traditional DLP is excellent when sensitive data matches known patterns: payment-card numbers, API keys, national identifiers, and predictable secrets. But the sentence “The board has approved the acquisition. Do not discuss Company X until Thursday” is sensitive for reasons a regex cannot express.
A semantic decision layer could evaluate whether content contains confidential business information, whether external sharing is allowed, and whether review is required. The same shape applies to phishing and business-email compromise, IAM decisions that depend on device and environment context, fraud screening, vulnerability prioritisation, and cloud-security activity.
Type-safe does not mean correct
TypeSafe markets Jev as unable to hallucinate. Its technical explanation is more precise: outputs conform to the schema defined by the application. If an application defines ALLOW, REVIEW, and BLOCK, Jev cannot return an unrelated paragraph or malformed tool call. TypeSafe notes its zero type-error figure is guaranteed by construction, not an empirical benchmark.
That is valuable, but it is not the same as correctness. A model can still return ALLOW when the correct answer was BLOCK. The Nexus evaluation makes this distinction concrete: its reported errors are semantic errors, not schema errors.
For security teams, decision models should be treated as probabilistic sensors, not infallible policy engines.
The cost of a wrong decision should determine the automation threshold:
Decision + confidence
        ↓
Security policy
        ↓
high confidence + low impact → automate
uncertain                    → investigate
high impact                  → stronger controls
irreversible action          → require authorization
Deleting spam and deleting a production database should never share the same confidence policy.
Jev is not a replacement for reasoning models
Jev is not designed to generate exploit code, conduct deep multi-step vulnerability research, or replace human judgment. It gives up arbitrary string generation in exchange for structured decisions.
The more useful architecture is specialised intelligence assigned to specialised jobs:
Signals
   ↓
Detection tools
   ↓
Decision model
   ↓
Reasoning model for uncertainty
   ↓
Independent verification
   ↓
Policy enforcement
   ↓
Action
This is not “Jev replacing GPT.” It is a potential new layer in systems that already need many small, context-dependent judgments.
The security question worth asking now
It is too early to call Jev a cybersecurity breakthrough. The most dramatic performance figures are vendor benchmarks; independent evidence is early and limited to a specific agent environment. Nexus itself lists important caveats around test-set size, AI-assisted labelling, and the need for further validation.
But the idea is significant. Security does not suffer from a shortage of data. It suffers from a shortage of attention and trustworthy decisions.
The question is not “can Jev replace our analysts or security models?” It is:
Which security decisions are currently too frequent, too fast, or too inexpensive to justify AI — and what changes if that constraint disappears?
SOC triage, agent guardrails, semantic DLP, phishing analysis, IAM risk, vulnerability prioritisation, fraud detection, and automated verification already make decisions. If decision models hold up under broader testing, semantic judgment could become a quiet part of security infrastructure: evaluating every alert, action, and transition in the background while deterministic policy remains responsible for enforcement.
Editorial assessment: Jev is extremely new. Treat TypeSafe’s performance figures as vendor results until they are independently reproduced. The Nexus benchmark is useful early third-party evidence, but it covers one agent environment rather than cybersecurity broadly. Security-critical implementations should retain deterministic authorization boundaries, independent verification, fallbacks, and human review for consequential actions.
Sources
- TypeSafe AI: Introducing System One Models & Jev — architecture, pricing, latency, workflow methodology, and stated caveats.
- TypeSafe workflow evaluation: Security Incidents — the incident context, decision stages, and response actions.
- TypeSafe workflow evaluation: Agent Trace Observability — agent-action and authorization checks.
- Nexus Agent: Jev, a boring classifier that unlocks a lot — early external guardrail evaluation and reported latency/cost figures.
- Vercel: TypeSafe AI’s Jev now available on AI Gateway — API behaviour and deployment context.
Related reading:





