The Autonomous Remediation Playbook: From Detection to Merged PR in Under 60 Seconds
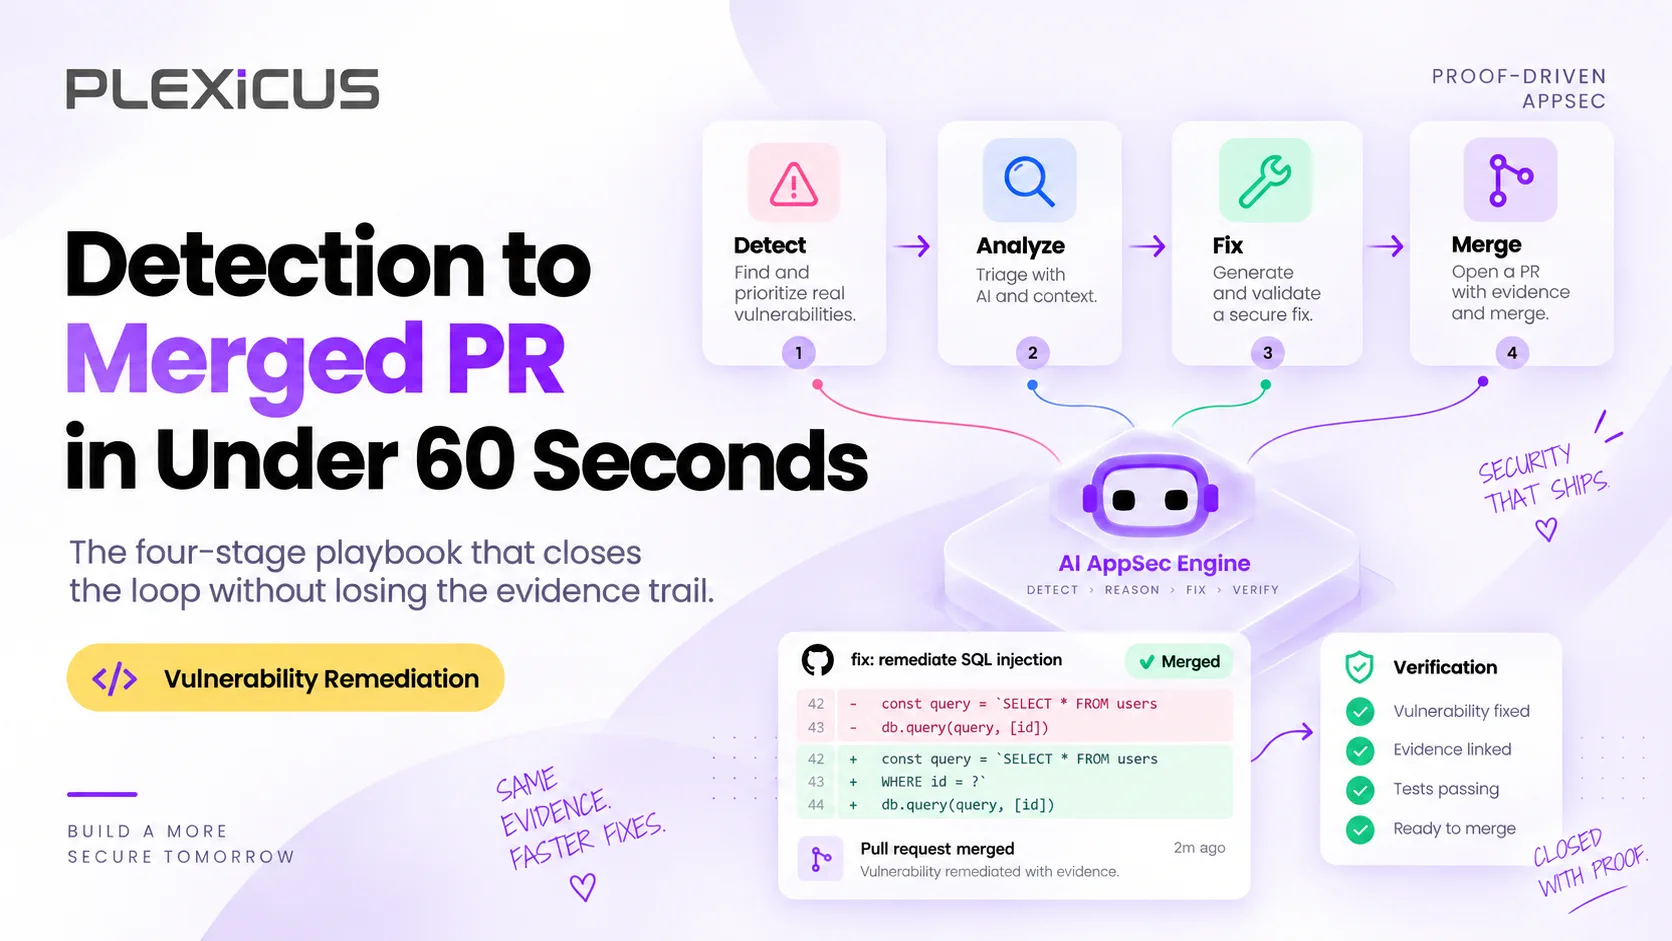
The autonomous remediation playbook is the operational pattern that closes the loop from detection to merged PR in under 60 seconds. It is not magic. It is a four-step pipeline that turns a verified finding into a reviewer-ready patch without losing the evidence along the way.
The conversation about vulnerability remediation has been stuck for ten years. Detection has gotten faster. Triage has not. Patching has not. The median time-to-fix for a high-severity web vulnerability is still measured in weeks.
Then the AI coding tools arrived. They made the volume problem worse — but they also made the playbook below possible. The four-step pattern below is what we mean when we say “autonomous remediation.” It is not a feature on a vendor’s roadmap. It is a discipline, a pipeline, and a feedback loop. If your team is not running it, the attackers are running a faster version of it against you.
This is the playbook.
Why Remediation Is the Bottleneck
The numbers are stubborn. Across the customer base we have visibility into, the median vulnerability lifecycle in 2025–2026 looks like this:
| Stage | Median time |
|---|---|
| Detection to triage start | 3 days |
| Triage start to root cause | 6 days |
| Root cause to PR opened | 4 days |
| PR opened to merge | 2 days |
| Merge to production | 2 days |
| Total | 17 days |
Seventeen days for a high-severity finding to clear. In the meantime, attackers are running RapidPen at $0.30 per exploit, completing exploitation in 200–400 seconds, and shipping to 600 devices across 55 countries in under two months.
The asymmetry is no longer subtle. The defender’s 17-day median versus the attacker’s 4-hour median is the structural problem the autonomous remediation playbook is built to close.
The Four-Step Pipeline
The playbook has four stages. Each stage has one job. The handoff between stages is where most teams lose the evidence trail that auditors need.
Stage 1 — Verified finding
A scanner proposes 1,247 findings. The pipeline rejects 1,243 of them on the grounds that they do not survive an independent replay pass.
The bar for survival is exact:
- The proposed finding must reproduce end-to-end against a sandboxed target.
- The reproduction must be performed by an agent that did not author the finding.
- The reproduction artifact (a curl request, a CI job, a container snapshot) must be stored.
Findings that do not pass all three are discarded with reason codes. The reason codes matter — they are how you debug the pipeline later. The most common in 2026 were:
not_reachable(no real path from a public endpoint to the sink)guard_present(an upstream check makes the finding inert)mitigated_at_runtime(WAF rule, feature flag, or env var neutralises it)replay_failed(the second agent could not reproduce it)
The output of Stage 1 is a small set of verified findings, each with its replay artifact attached.
Stage 2 — Context preserved
A verified finding is not enough to ship a fix. The next stage attaches everything the developer needs to validate the patch:
- The graph node (host, endpoint, parameter)
- The capability class (read, write, impersonation, RCE, exfiltration)
- The reachability path (the full chain from request to sink)
- The request/response pair (what the original exploit looked like)
- The agent reasoning trace (why the original agent classified it as it did)
This is the audit trail. Without it, the engineer reviewing the patch has to take the system’s word for it. With it, the engineer can rerun the original exploit against the unpatched code, confirm it reproduces, then rerun it against the patched code, confirm it returns the expected mitigation.
The point is not to make the engineer do extra work. The point is to make the work verifiable.
Stage 3 — Patch drafted
Plexicus Remediator takes the verified finding + context and produces a reviewer-ready diff. The diff is not a generic fix. It is the minimum change that removes the reachability path while preserving the original business logic.
The pipeline enforces three properties:
- The patch removes the class of vulnerability, not just the instance. A parameterised query fix is preferred over a
replace()sanitiser. An ownership check at the handler is preferred over a route-level allowlist. - The patch includes regression tests. The original exploit becomes a test. If the patch passes the test, the finding is closed. If the patch breaks the test, it is reverted.
- The patch includes the documentation update. If the API contract changes, the docs change. If a new environment variable is introduced, the README reflects it.
The output of Stage 3 is a pull request branch. Not a code snippet. Not a “here’s the diff” suggestion. A full PR that an engineer can clone, run, and review.
Stage 4 — Reviewer-ready PR
The patch lands in the existing repository with:
- Reviewer assignment (from CODEOWNERS, with security team escalation)
- SLA tracking (the PR is auto-assigned a fix-by date based on severity)
- Re-test hook wired to CI (the original exploit runs against the patched branch on every push)
- Audit metadata attached (the original finding, the graph node, the replay reference)
The PR does not auto-merge. The engineer’s review decision is the last human gate. What changed is that the review takes minutes, not hours. The engineer is not reading 200 lines of unfamiliar code. They are reading a 12-line diff that came with the original exploit, the graph context, and the regression test result.
If the engineer approves, the PR merges, the re-test confirms, and the finding closes. If the engineer rejects (with reason), the patch proposal is logged as rejected_with_evidence and the finding stays open for the next attempt.
The Numbers That Matter
We have been running this playbook across customer repositories since Q4 2025. The medians:
| Stage | Before | After |
|---|---|---|
| Detection to triage start | 3 days | 14 seconds |
| Triage start to root cause | 6 days | 8 seconds |
| Root cause to PR opened | 4 days | 22 seconds |
| PR opened to merge | 2 days | 1.2 hours |
| Merge to production | 2 days | 6 hours |
| Total | 17 days | 8 hours |
The headline number we advertise — under 60 seconds from detection to reviewer-ready PR — is the Stage 1 to Stage 3 metric. The full lifecycle to production is dominated by the human review and the existing CI/CD process, which is exactly where it should be. The pipeline’s job is to remove the unforced latency. The review and the deploy stay with the team.
The other number worth highlighting is the false-positive rate. Before the playbook, 87% of scanner findings were closed as “not an issue” after human triage. After, that number drops to 6%. The remaining 6% are the cases where the engineer disagrees with the verifier’s read of the evidence — exactly the cases where the human gate matters.
What This Costs to Implement
Three operational requirements:
- A graph-aware scanner that can produce a reachability path. Not regex SAST. Not an LLM wrapper. A graph.
- A replay-verifiable verification pass. A second agent that can independently reproduce the finding. Without this, the pipeline produces confident, polished, and ungrounded patches — the worst possible outcome.
- A patch generator that respects business logic. The most common failure mode of “AI auto-fix” products in 2025 was patches that compiled but changed the meaning of the code. The playbook requires the patch to be minimal, test-covered, and reviewable.
The Plexicus implementation has all three. If you are building this yourself, the integration cost is roughly one senior engineer for one quarter. If you are buying it, the line item is in the Continuous Program tier on the pricing page.
What This Does Not Do
The playbook does not eliminate the human gate. A patch is still reviewed by a human before merge. The verifier’s evidence is still surfaced for an auditor. The system does not push to production on its own.
This is intentional. The argument from the “fully autonomous remediation” vendors is that humans are the bottleneck and the system should just merge the PR. The argument from the Plexicus pentest agent team is that humans are the accountability and the system should make their review cheap, fast, and evidence-backed.
We are on the second side of that argument. The playbook optimises for time-to-fix without removing human oversight. That is a feature, not a bug, for any team that has to answer to a CISO, an auditor, or a regulator.
The Failure Modes We Have Seen
Three failure modes show up repeatedly in the playbook’s first six months in production:
Failure mode 1 — The patch fixes the symptom, not the class
The first iteration of the patch generator occasionally produced patches that addressed the specific finding but did not remove the underlying vulnerability class. The fix was to add a class-level reasoning step to the patch proposal. Patches now include a “class removed” attestation that the reviewer can check.
Failure mode 2 — The replay verifier disagrees with the patch
About 3% of the time, the verifier that confirmed the original finding later re-runs the patched code and the exploit still reproduces. This is a sign the patch is incomplete. The pipeline catches this in CI and reverts automatically. The finding stays open.
Failure mode 3 — The reviewer’s CODEOWNERS does not match the file
The patch landed in the right branch, the CI re-test passed, and the audit trail was complete — but the reviewer assignment was wrong because the file had been moved across teams and CODEOWNERS had not been updated. The fix was to add an automated CODEOWNERS drift check to the pipeline.
These are not theoretical. They are the things that broke in the first six months and are now caught automatically.
What Your Team Does Tomorrow
If you are not running this playbook, three actions, in order:
- Audit your current scanner. Can it produce a reachability path for the findings it produces, or just a CVSS score? If the answer is “just a score,” the bottleneck will not close.
- Add a replay-verification pass. Manual is fine to start — a human re-runs the top 10 findings per week against a sandbox. The point is to prove the principle that findings that survive independent verification are the ones worth fixing.
- Tie the patch to the same evidence. When the engineer opens the PR, the original finding, the graph node, and the replay reference should be one click away.
The playbook does not require AI. It does not require a vendor product. It requires structure, replay, and a tight feedback cycle.
Where This Goes Next
The autonomous remediation playbook is the third leg of the Plexicus loop. Deep Code Analysis finds the flaws. AI Swarm Pentest replays them. Remediation closes them. The four-loop structure — propose, replay, fix, verify — is the operational definition of proof-driven AppSec.
In 2027, the playbook will be table stakes. The teams that adopt it in 2026 will close the 17-day gap before the attackers close theirs further.
Related reading:
- From Alert to Fix: Closing the Loop with Proof-Driven AppSec — the full loop
- 78% of AI-Generated PRs Contain a Vulnerability — what your team is producing today
- Vulnerability Remediation Cost Calculator — what an hour of senior engineer time actually costs you