Gemini 4 Carbon Benchmarks: Demand Deployment Evidence
Turn AI security benchmark claims into a scoped evaluation with reproducible findings, reviewed patches and deployment retests.
Beyond ASPM
Proof-Driven AppSec for teams building with AI
Plexicus uses AI Swarm Pentest to explore authorized application paths, validate what is exploitable, and give teams evidence they can use to prioritize remediation.
Explore AI Swarm PentestOn October 28, Google reported security benchmark results for Gemini 4 Carbon: 88.2% on SEC-bench Pro, 54.8% on ExploitGym and 71.0% on CWE-bench. Google says it evaluated these external benchmarks without guardrails. Google’s announced rollout starts with selected cyber defenders through its Fairwind Program; the announcement does not establish broad developer access.
Those are vendor-reported evaluation results. Your application needs a different acceptance record: the authorized target, the observed failure, the patch and the outcome when the same test runs again. A model score can inform a shortlist. A deployment decision needs evidence tied to your system.
Read the task before comparing the score
The three percentages address different tasks. They do not describe three successive completion rates for one shared set of production vulnerabilities.
| Benchmark named by Google | Reported result | Question for your evaluation |
|---|---|---|
| SEC-bench Pro | 88.2% | What target, task snapshot and checker establish a valid discovery? |
| ExploitGym | 54.8% | What starting information, environment and success condition define exploitation? |
| CWE-bench | 71.0% | Which checks establish that a patch fixes the issue and preserves behavior? |
The SEC-bench project, ExploitGym repository and CWE-bench site document their own evaluation designs. Do not infer the exact snapshot, denominator or agent configuration of Google’s run from a current public homepage. We have not independently reproduced Carbon’s results.
An average across these percentages would create a metric with no defined meaning. Multiplying them would also assume a shared sample and dependent workflow that the announcement does not establish. Keep each result attached to its task and evaluation conditions.
Give your assessment a bounded target
Begin with one application flow that matters to your team. Name the deployment revision, test accounts, permitted interfaces and exclusions. Use synthetic data. Define who can stop the exercise and which actions need separate approval. A production hostname by itself is not an adequate scope statement.
Choose a known regression fixture and a representative business flow. The fixture checks whether the assessment can recover a failure whose conditions you understand. The business flow checks whether the output answers the question your team actually needs to resolve. Neither result should be stretched into a promise of complete coverage.
This follows the evidence discipline in our Proof-Driven AppSec workflow. A finding should give a reviewer enough context to repeat the observation under the same authorized conditions.
Keep discovery, validation and repair connected
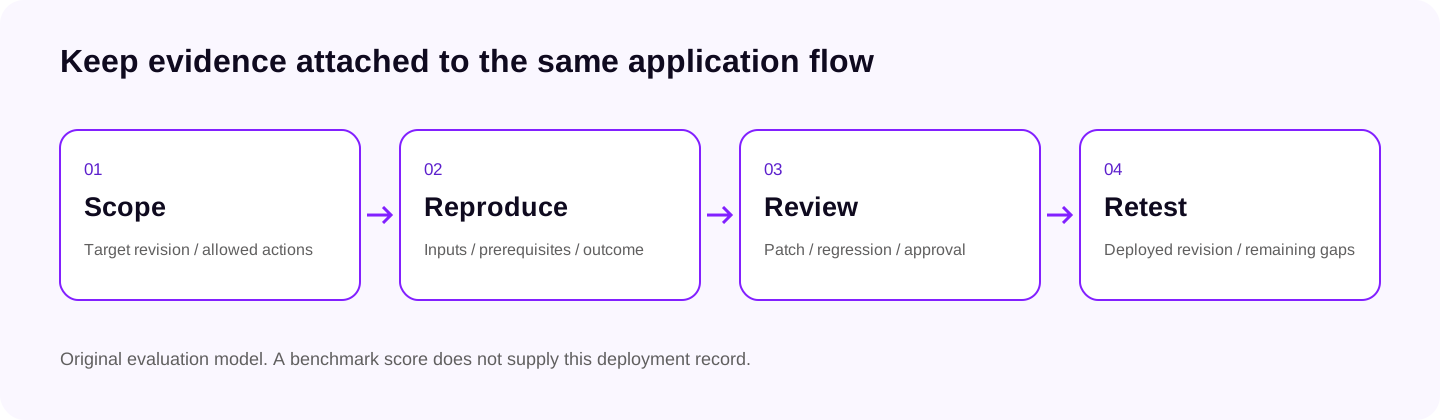
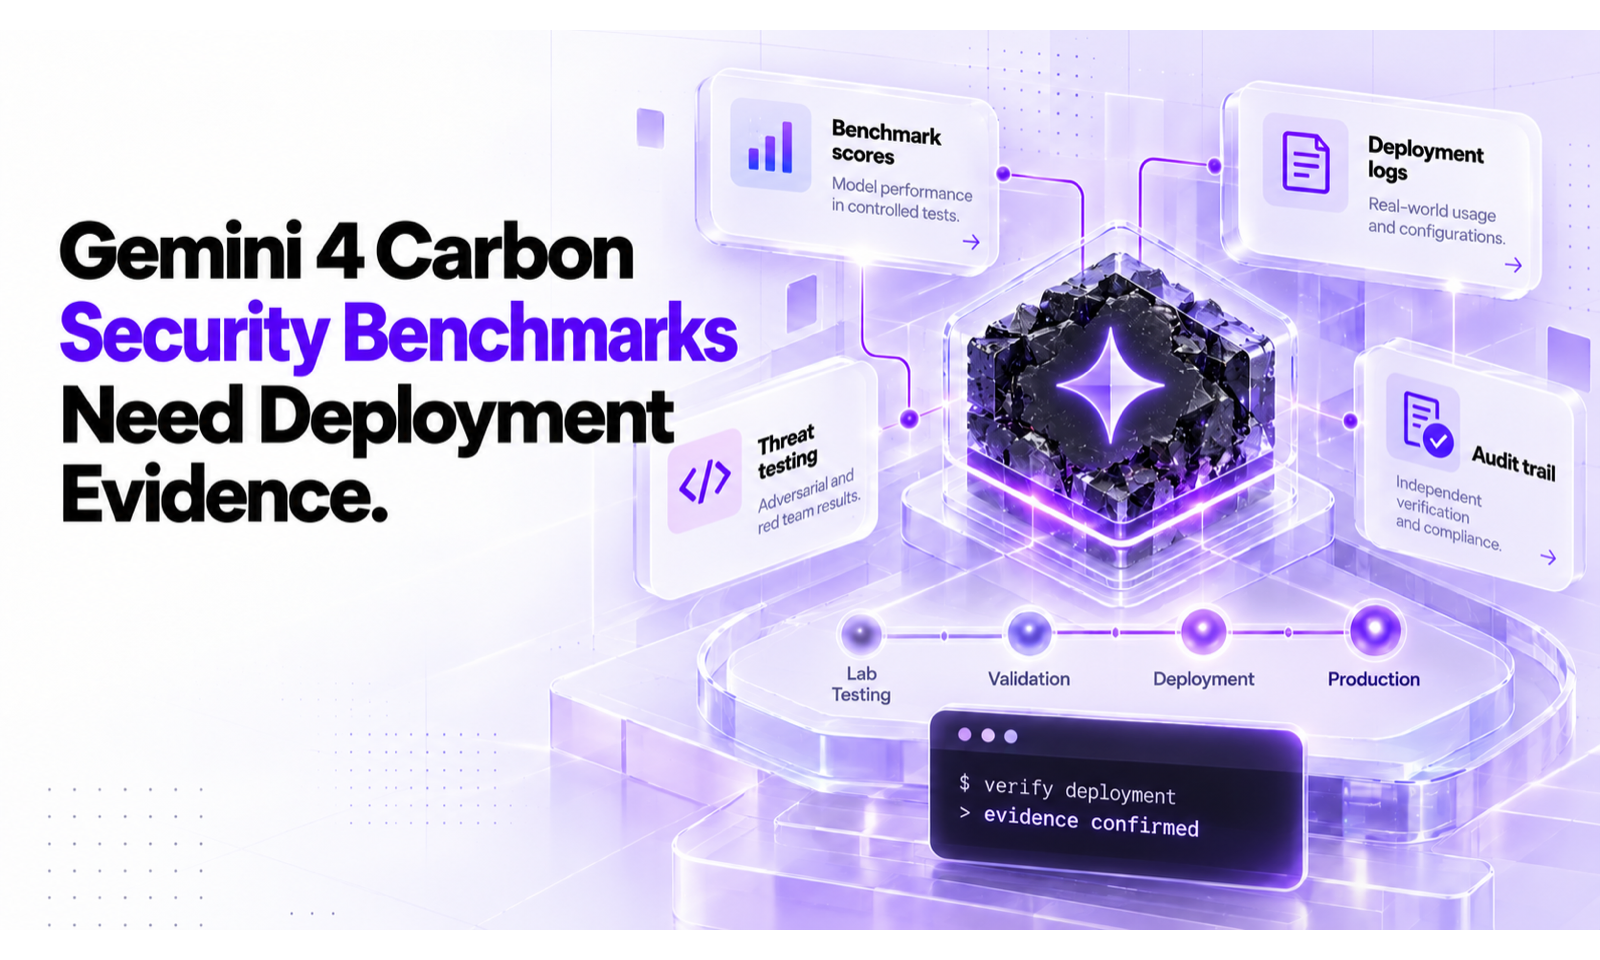
Original evaluation model. This diagram is not Google’s benchmark harness or a claim that Plexicus uses Carbon.
For discovery, retain the relevant input, code location or endpoint and the reasoning that connects them. Mark uncertainty explicitly. A suspicious pattern is a useful hypothesis even when it has not become a reproduced finding.
For validation, retain the minimum harmless reproduction that establishes the claimed behavior. Record prerequisites such as permissions, configuration and reachable inputs. A timeout, blocked tool call or unavailable dependency is an incomplete result. It does not prove the application resists the attack.
For repair, require a reviewable diff, a test for the original failure and checks for legitimate behavior. Repeat the observation against the patched deployment. Record a failure to reproduce separately from evidence that the root cause was removed. Our remediation playbook describes the handoff between the proposed fix and reviewer approval.
Preserve the conditions that change the answer
The model is one part of an assessment system. Its tools, permissions, context, time budget and execution environment also shape the result. Retain those settings with the output so a later reviewer can understand what was tested.
A benchmark evaluated without guardrails does not establish the behavior of a differently constrained product configuration. Equally, a permitted laboratory action does not authorize the same action against a customer system. Specify the allowed test behavior before the run and report blocked work honestly afterward.
Use a compact evidence packet:
- Target revision, configuration and authorized scope.
- Model and tool configuration, budget and relevant restrictions.
- Reproduction inputs, prerequisites and observed outcome.
- Reviewed patch, regression result and legitimate-flow checks.
- Deployed revision, retest outcome and unresolved questions.
The packet makes the review portable across model changes. It also exposes gaps that a single headline score hides. The distinction between an analysis result and a verified outcome is central to Deep Code Analysis.
Use Plexicus to define a reviewable outcome
Plexicus presents AI Swarm Pentest as a scoped application and API assessment, and its remediation workflow describes reviewable fixes with verification retests. Bring a specific flow and an evidence contract to the engagement. Ask which observations, patch artifacts and retest records fall inside the agreed scope.
This article does not establish a Carbon integration, a reproduced Carbon benchmark run or a performance comparison between Plexicus and Google. The practical product question is whether your assessment produces evidence your engineers can inspect and use to approve a change.
Ready to evaluate one application flow? Contact Plexicus with the authorized target and the outcome your team needs to verify.
Sources